DGX Spark vs RTX 4090 vs Mac mini: Why I Kept My 4090
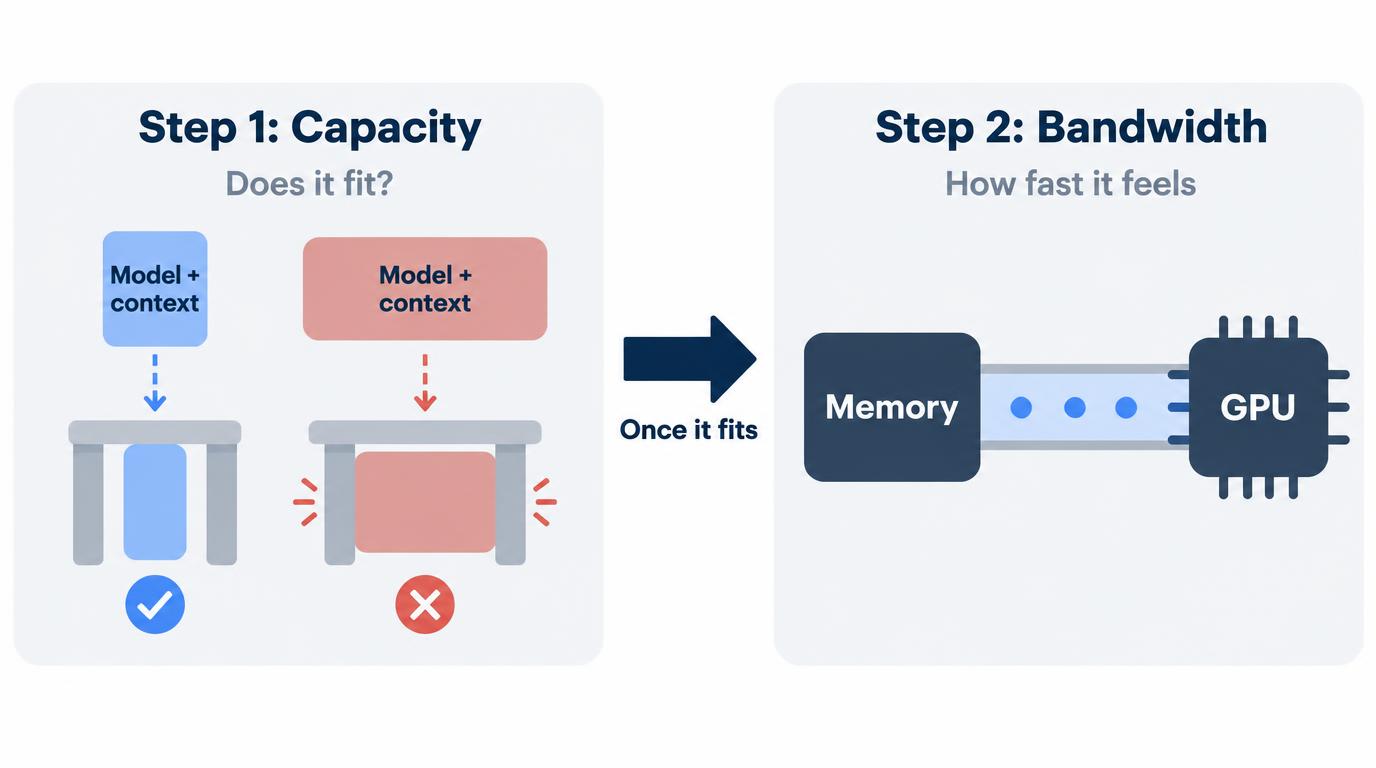
DGX Spark: 128GB at 273GB/s. RTX 4090: 24GB at about 1TB/s. My measured 4090 VRAM numbers show when capacity matters, and why I haven’t bought a Spark.
DGX Spark: 128GB at 273GB/s. RTX 4090: 24GB at about 1TB/s. My measured 4090 VRAM numbers show when capacity matters, and why I haven’t bought a Spark.
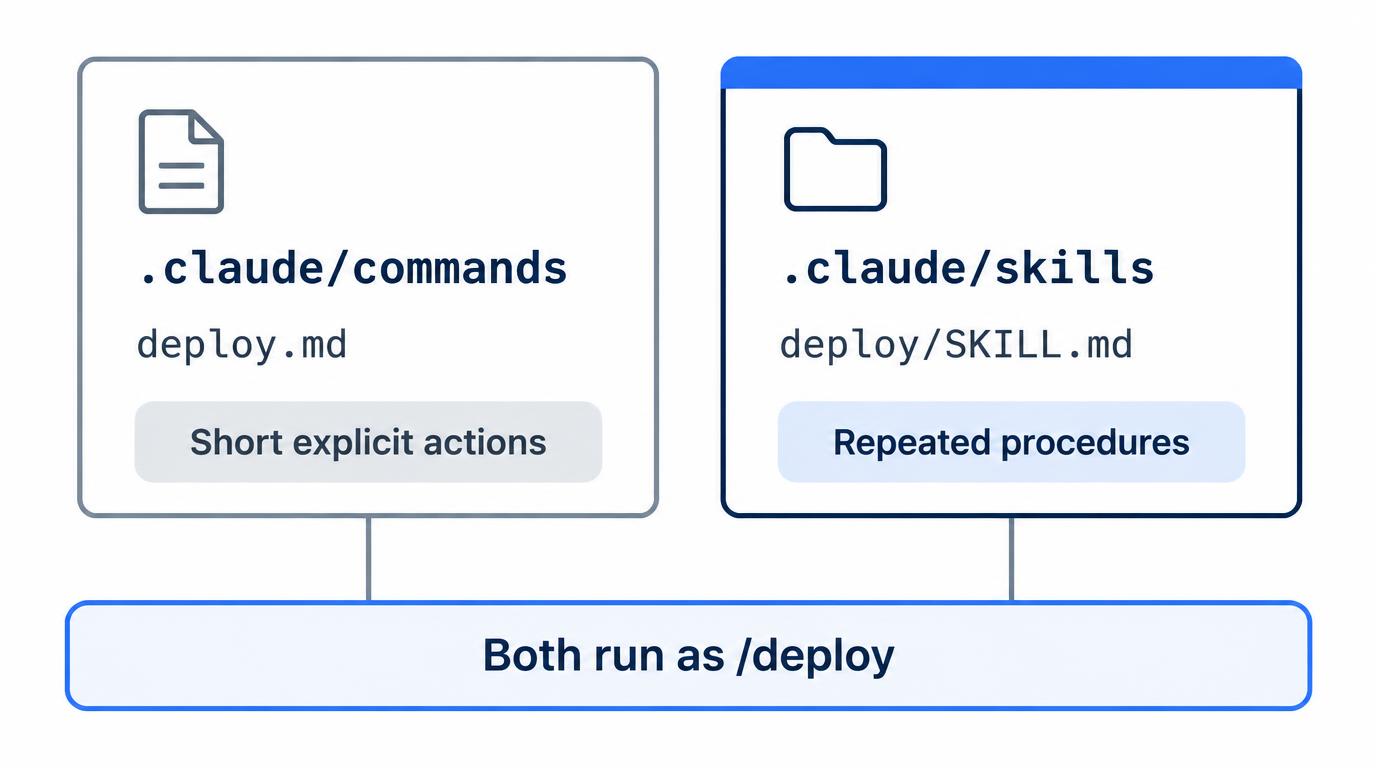
/project: fails because Claude Code merged custom commands into skills. What changed, what broke when I moved mine, and the description fix that helped.
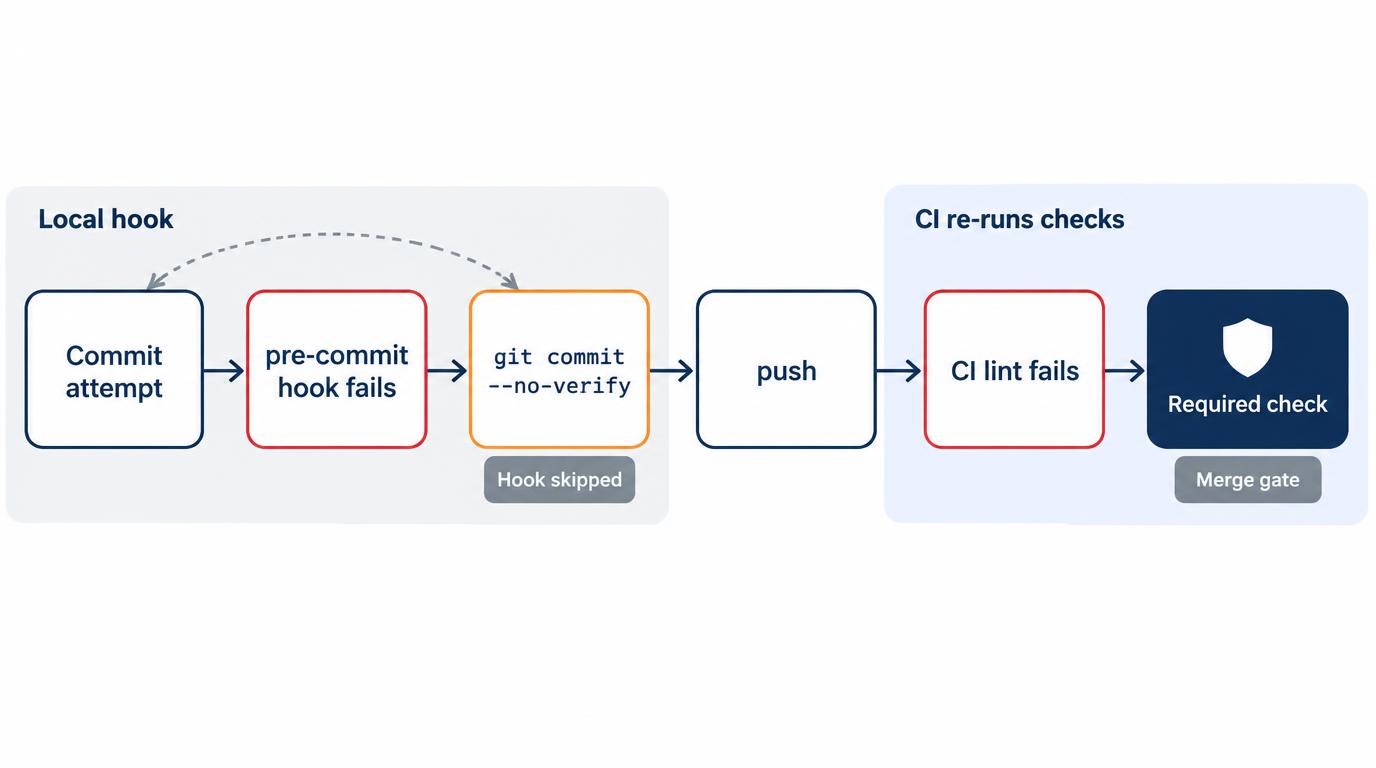
git commit –no-verify skips pre-commit and commit-msg hooks, so no hook can stop it. My AI agent used it; CI as a required check caught the lint error.
Claude down mid-task? A failed agent response can still leave edited files. When switching to Codex is safe, what –fallback-model covers, how to resume.
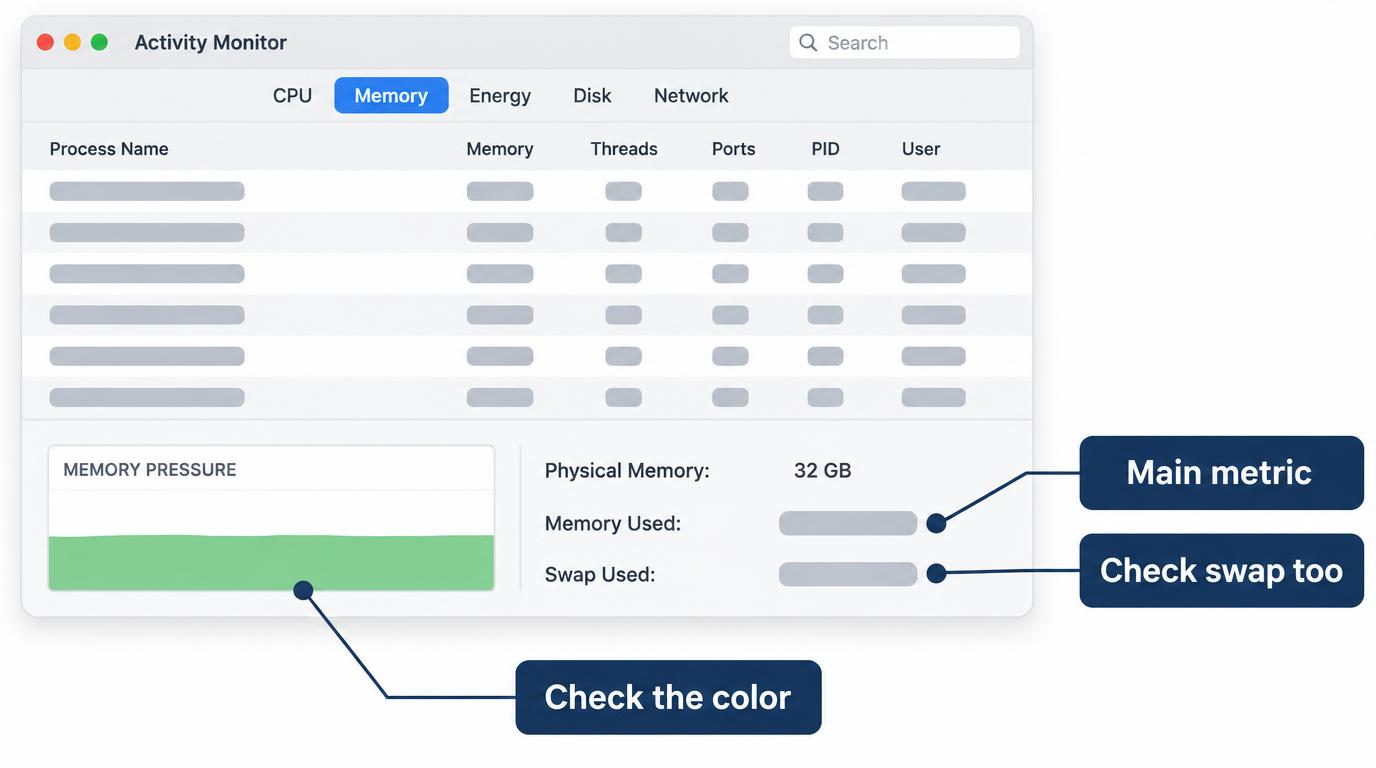
With coding agents and Docker running, my 32GB Mac mini M6 reached the low 30s of GB. If your dev work fits in 32GB, get the M6; past that, the M5 Pro.
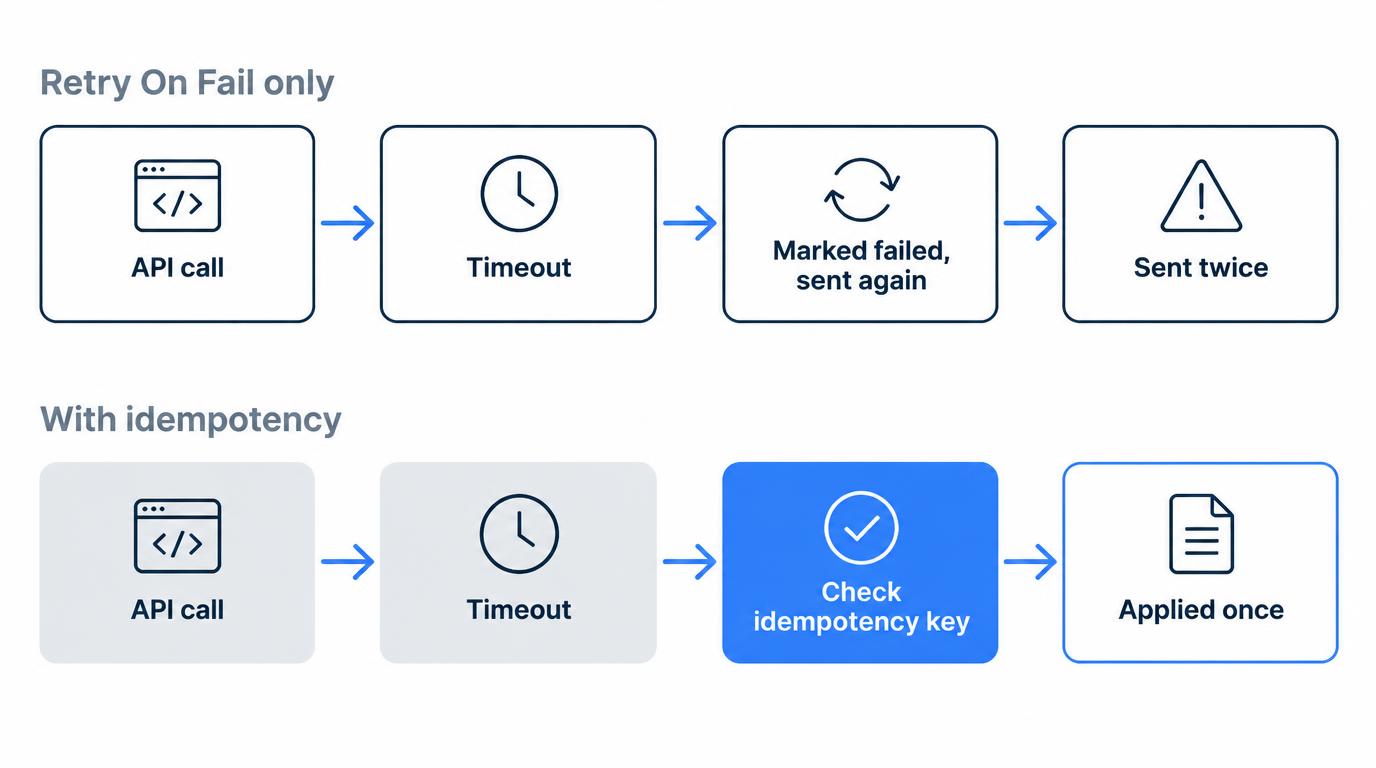
n8n Retry On Fail re-runs the whole node, every item included, after a timeout, even when the first call landed. Why it duplicates, and how to fix it.
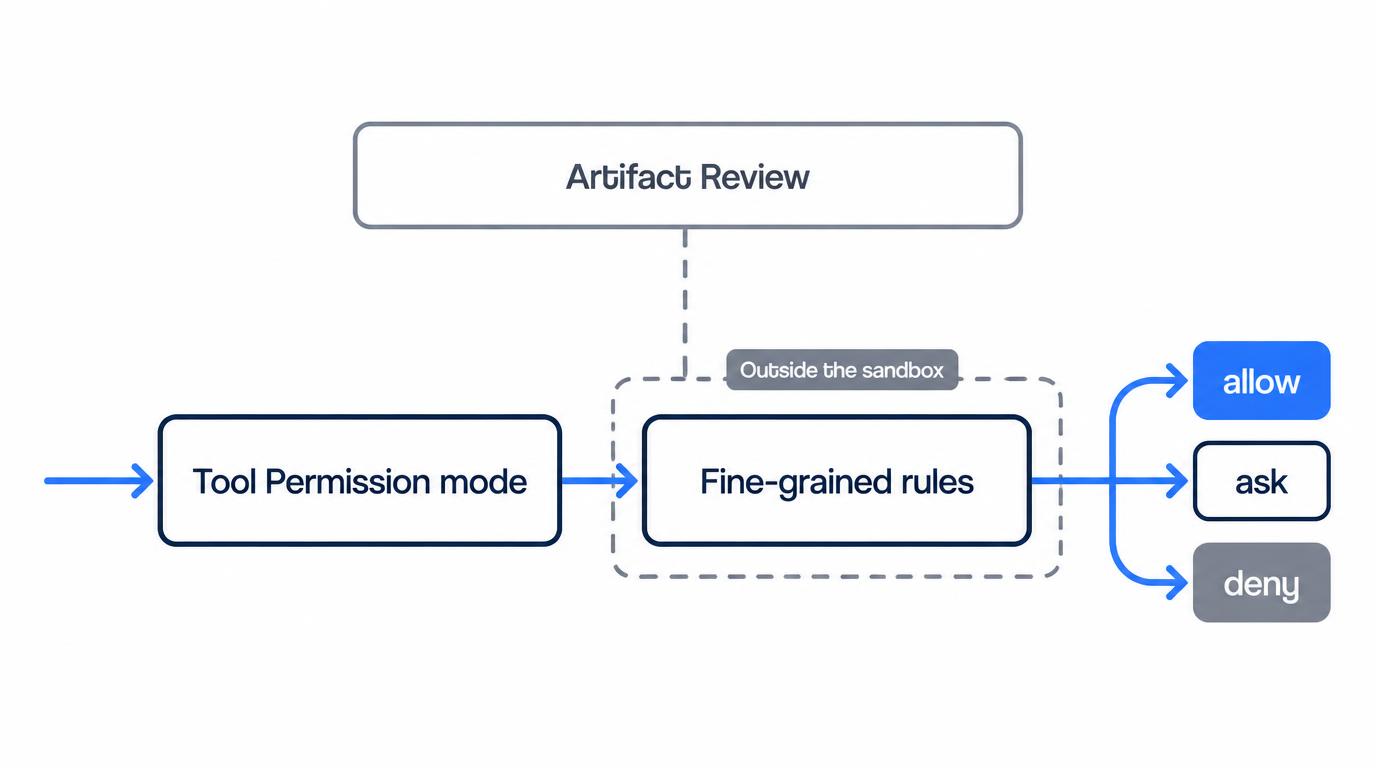
Use agy –dangerously-skip-permissions, but check your ask rules if it still asks; over 5 runs per mode, review mode stopped 4 actions I hadn’t approved.
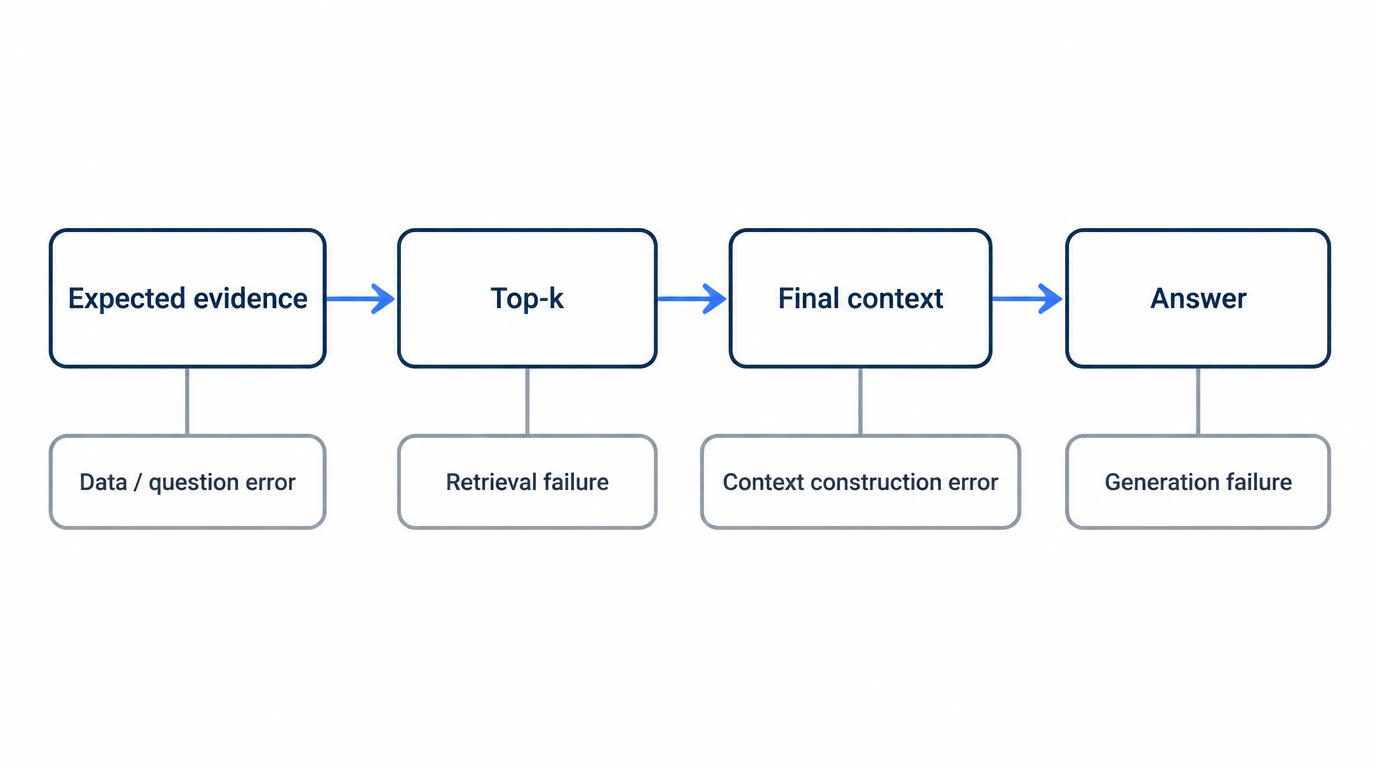
Wrong RAG answer? Find the right chunk in the top-k list, then in the prompt. In our 30-question run, heading paths halved retrieval misses; accuracy held.
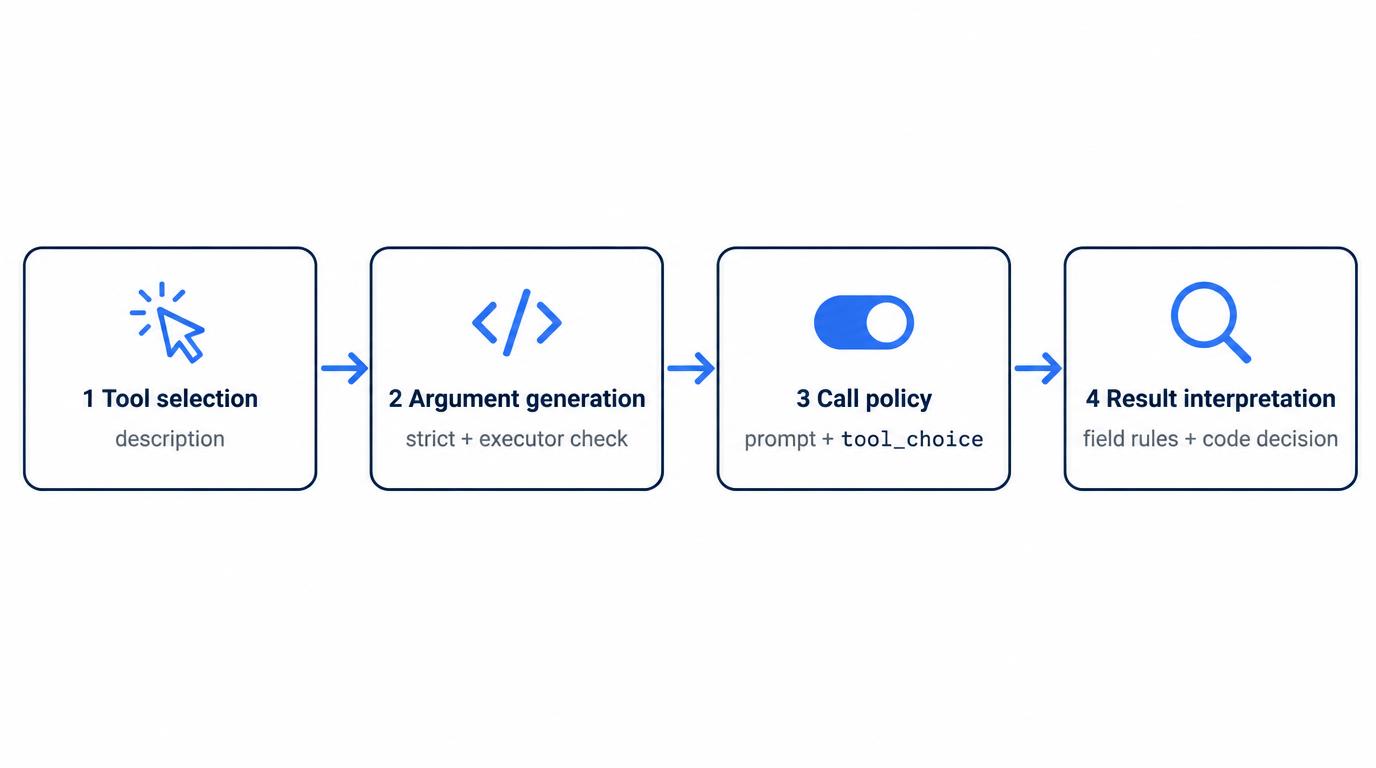
My agent picked the wrong tool in 6 of 20 runs. Cutting tools didn’t help; overlapping descriptions were the cause. Adding ‘when not to use’ cut it to 1.
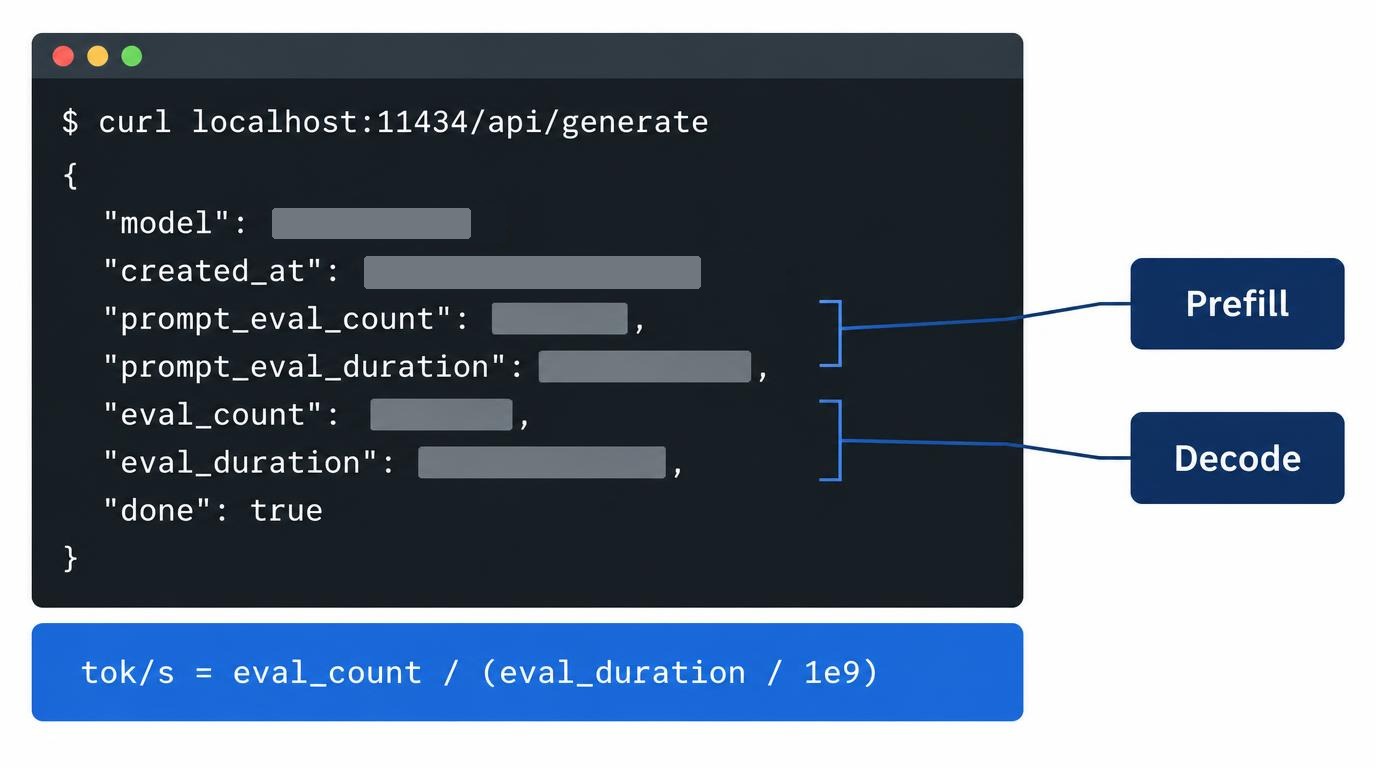
On one RTX 4090 with one user, vLLM and llama.cpp generate at about the same rate; vLLM pulls ahead with many concurrent users. My trial and the numbers.